Post go-live
Most implementations do not end at cutover. superglue turns the ongoing flows into scheduled tools that run without you and tell you when they fail.
Typical ongoing flows:
- The client runs old and new systems side by side for a period.
- Other applications still feed the old system.
- A subsidiary stays on the legacy product.
Build a sync
Section titled “Build a sync”-
Describe the flow to the agent as you would to a colleague. Include the direction, the trigger and what counts as a conflict:
Every night at 02:00 Europe/Berlin, copy new and changed customers from GP to Intacct.GP is the source of truth until 31 January. Skip customers already changed in Intacctthat day and list them in the result. -
The agent builds and tests the tool with you and shows a real result.
-
Approve the first write when the agent asks for it.
The Build an integration playbook covers this workstream. Select it or just describe the outcome.
Incremental syncs
Section titled “Incremental syncs”Incremental syncs keep a checkpoint between runs, such as the last processed timestamp. Each run picks up where the previous one stopped. The agent sets this up when the flow needs it.
Schedule the sync
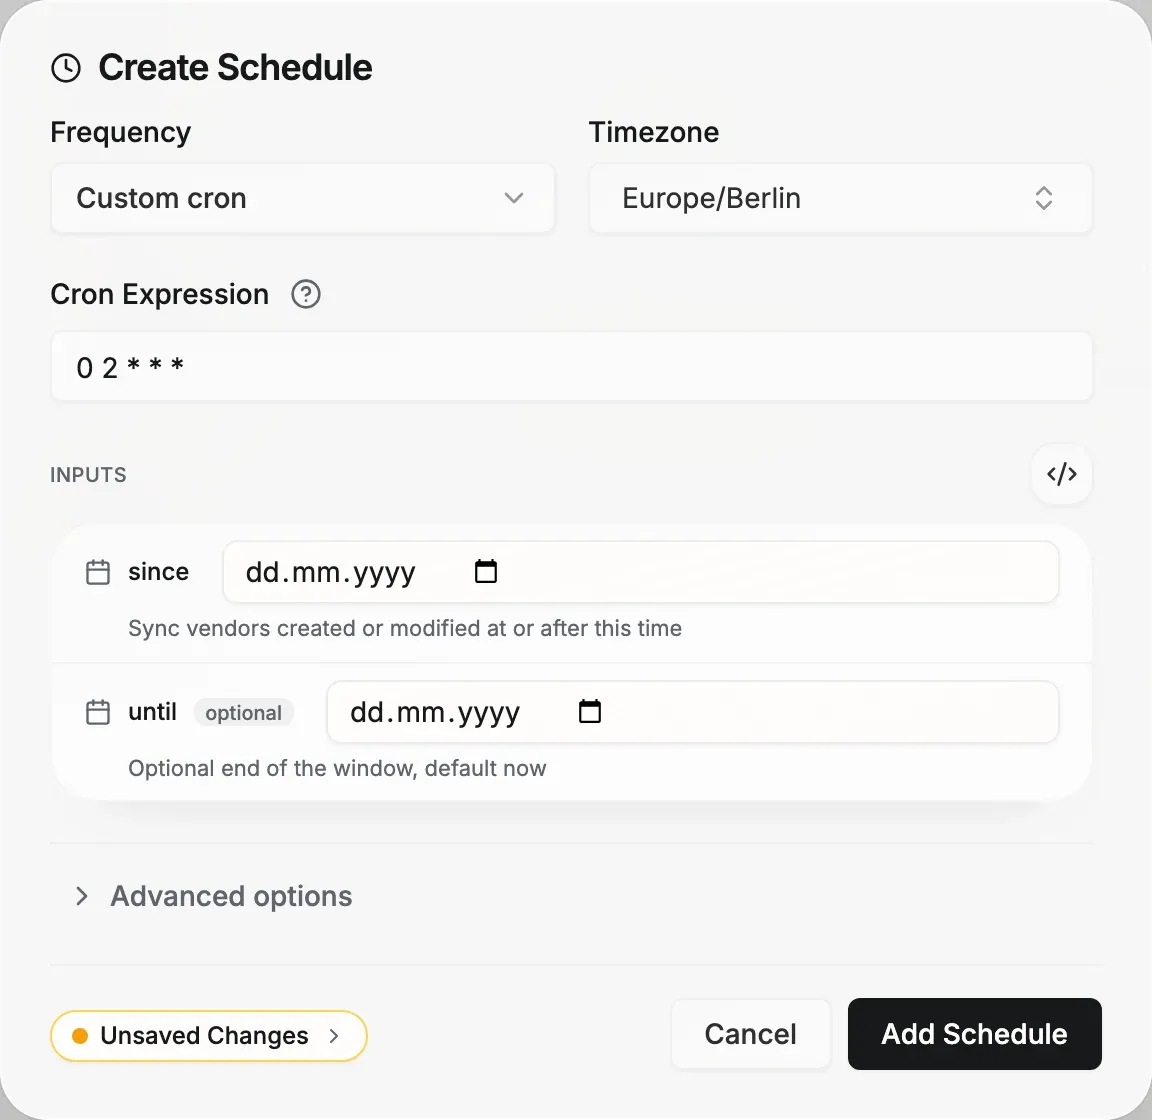
Section titled “Schedule the sync”- Open the saved tool and select Schedule.
- Choose the frequency and the timezone. For a fixed time such as 02:00, choose Custom cron.
- Enter the input the run should use.
- Select Add Schedule.
Scheduled runs act as the person who created the schedule and use the connection pinned in the schedule. Pin the client’s production connection explicitly.
Trigger on events
Section titled “Trigger on events”Some flows are triggered by events rather than time, such as an approved invoice in the new ERP that must post back to the old one. Use an incoming webhook for these flows. See Deploying a tool for schedules and webhooks.
Get alerted when a run fails
Section titled “Get alerted when a run fails”Set up notifications under Settings so failures reach you without watching the dashboard:
- On failure sends a Slack message or email as soon as a scheduled run fails, with the failed step and a link to investigate.
- Daily and weekly summaries list successful and failed runs per tool, which suits a client status email.
Filter rules by tool name pattern, for example contoso-*, so each engagement’s alerts go to the right channel. See Notifications.
Investigate and repair a failed run
Section titled “Investigate and repair a failed run”- Open the run under Runs.
- Select Investigate. The agent opens with the run loaded, explains the failure, and proposes a fix.
- When the fix changes the tool, the agent tests it before proposing the edit. The previous version stays in the tool’s version history.
Typical causes after go-live are a changed field in the target, a new code value in the source, or an expired connection secret.
Wind down after parallel run
Section titled “Wind down after parallel run”When parallel run ends, disable the schedule instead of deleting the tool. The run history stays available for the client’s audit, and the tool can be reenabled if the timeline slips.